Rune Infer
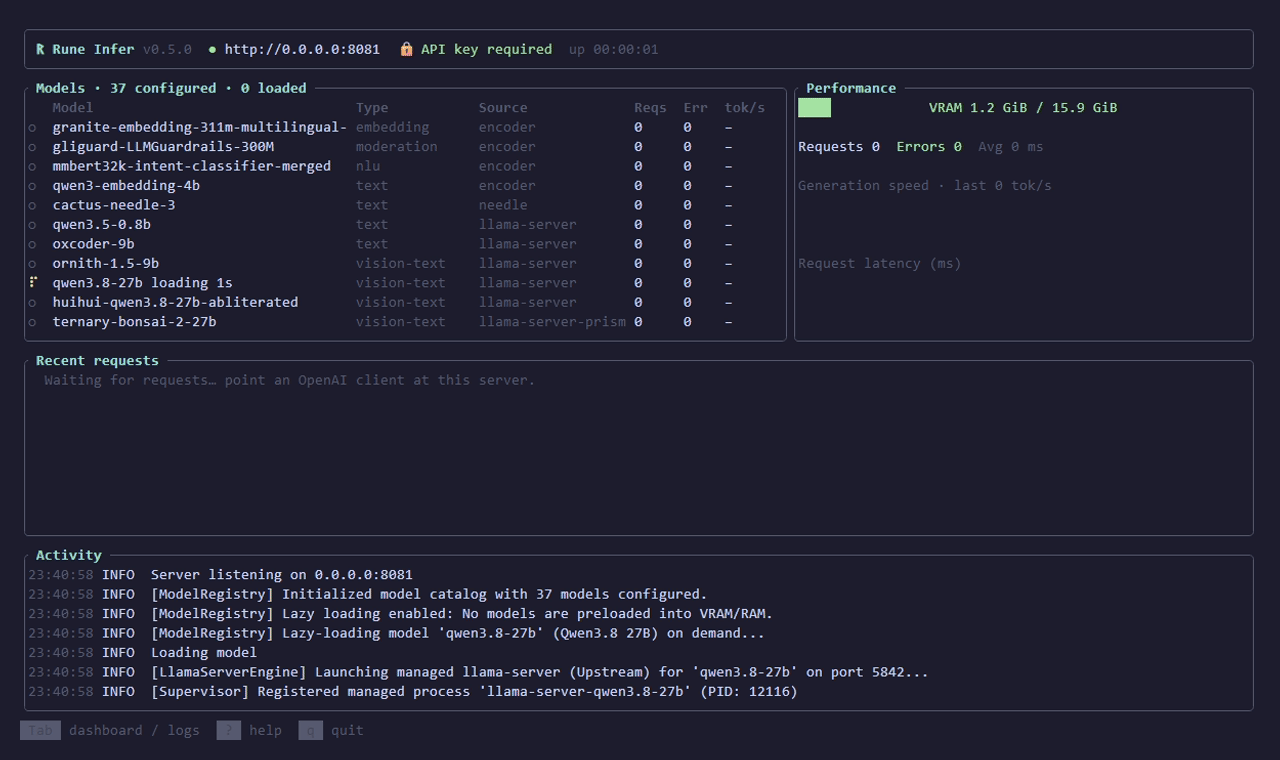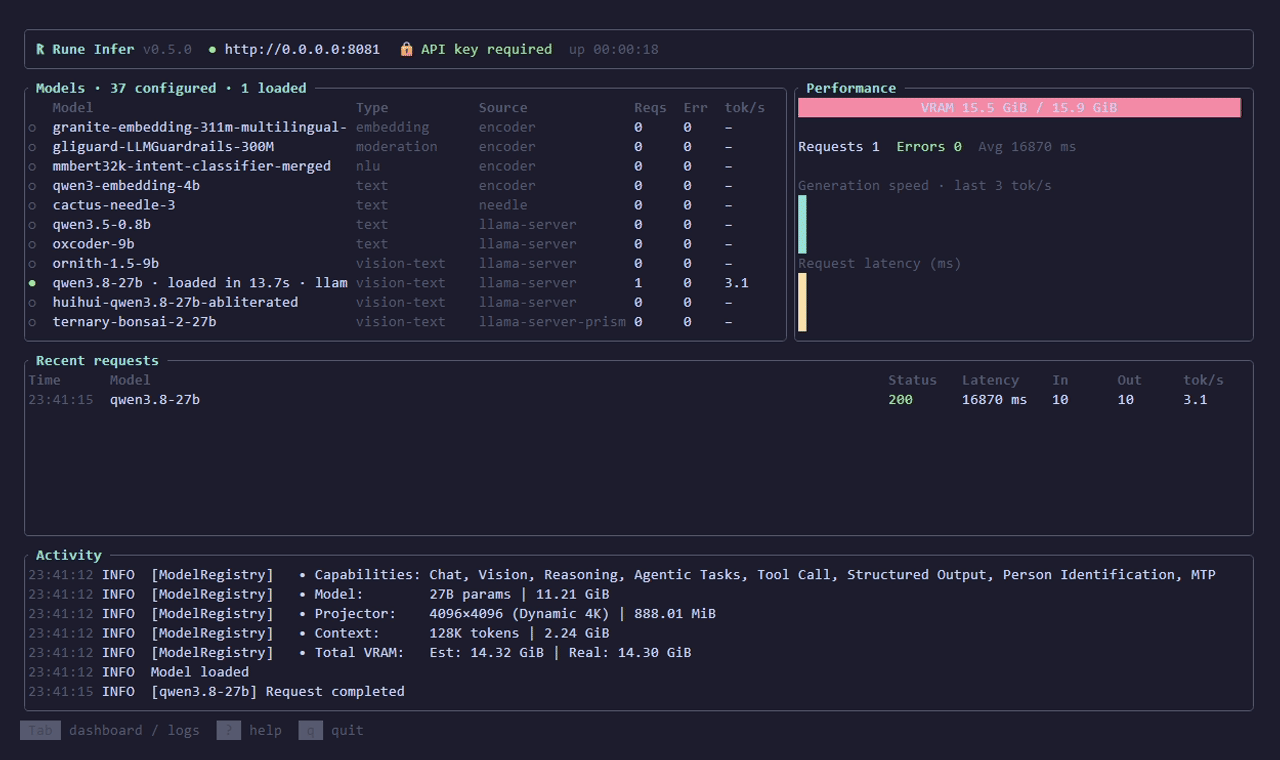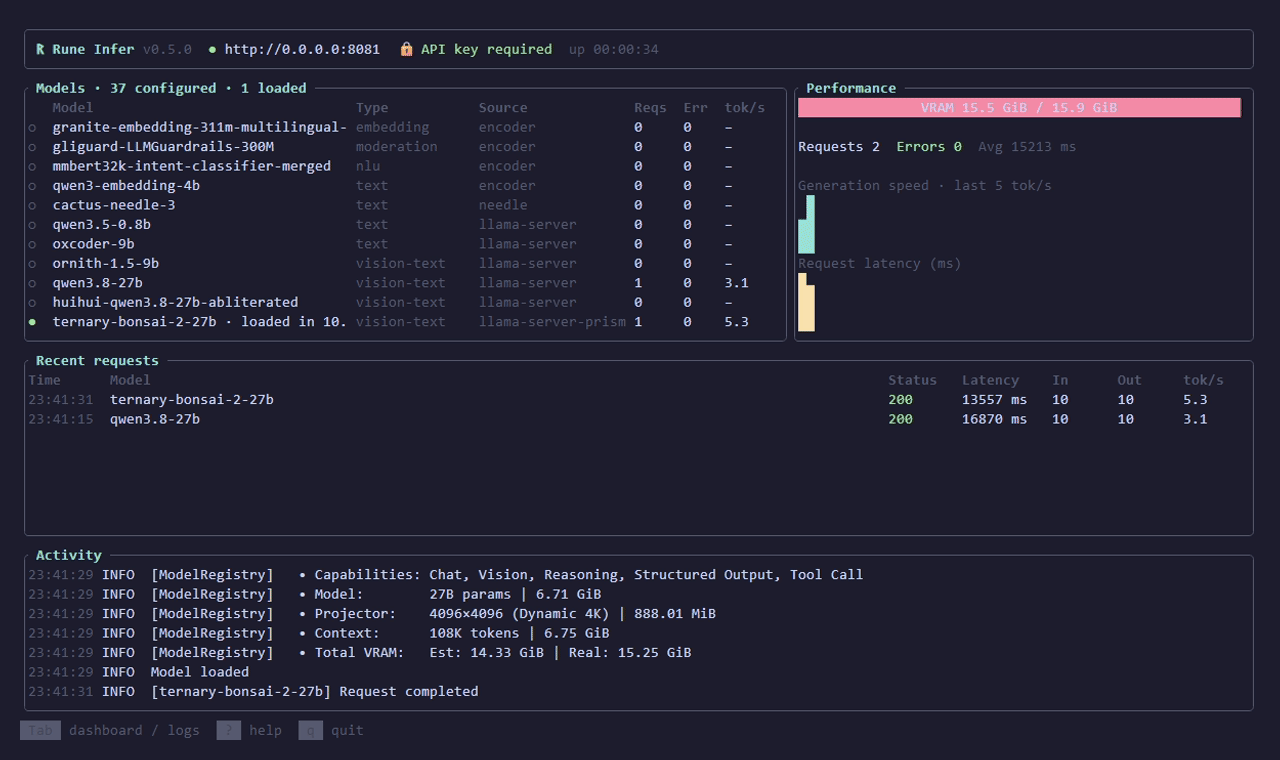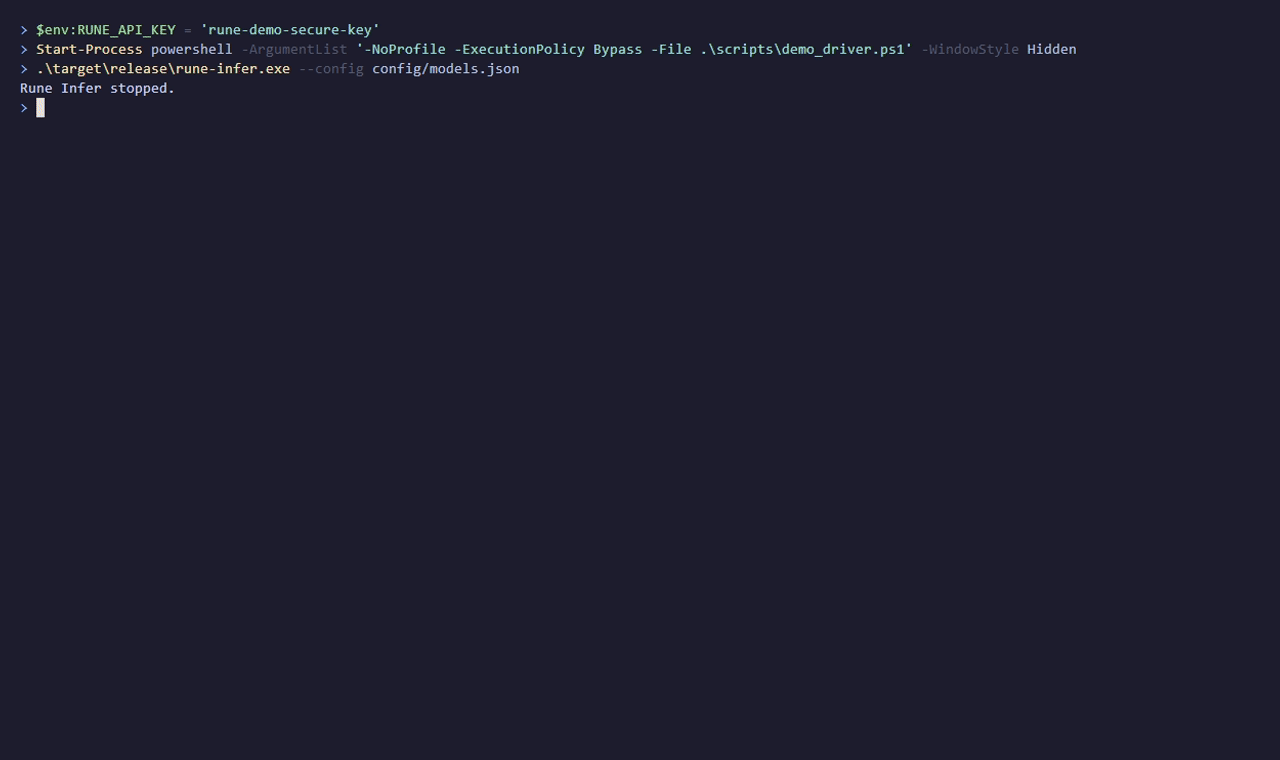
High-performance, single-binary AI model gateway unifying local GGUF engines and cloud APIs with pre-flight VRAM budgeting.
- Rust
- GGUF
- WASM
- Axum
Overview
Rune Infer loads quantised models and serves them over a local socket or straight from the browser through WebAssembly. It features pre-flight VRAM budgeting, LRU model unloading, and process isolation so a failing model cannot crash the host.
Capabilities
- 01
VRAM Budgeting
Pre-flight memory checks ensure models fit comfortably in available GPU/CPU memory.
- 02
Zero-Crash Isolation
Isolated execution engines guarantee that model exceptions never bring down the host gateway.
- 03
Runs Anywhere
Compiles to native binaries, container images, and WebAssembly modules.
Releases
- v1.4.0Current release
- v1.3.0